Evan SunLet's connect
Selected Work

Data applications & recommendation systems

JobPilot

A career workflow that normalizes job postings, explains candidate fit, and produces reviewable application materials.

Supporting project · Hosted Streamlit app was sleeping at the latest availability check
PythonStreamlitTF-IDFGreenhouse API
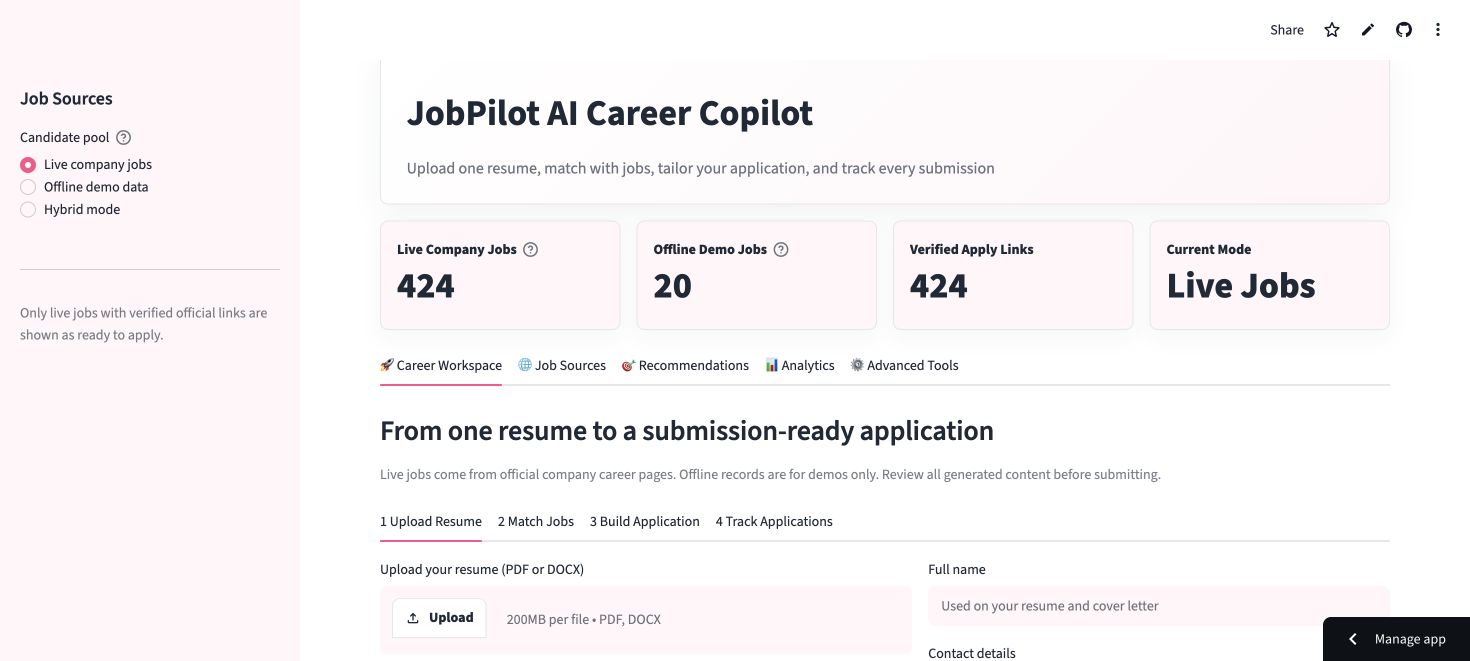
JobPilot workspace showing job-source options and candidate application workflow

Historical project material · See source notes below

The problem

A Python / Streamlit application connects Greenhouse job ingestion, normalized records, candidate retrieval, hard filters, weighted ranking, human-reviewed drafts, and CSV-backed application states.

How can a candidate inspect why a job ranks well and move from discovery to a reviewable application package?

Job discovery mixes duplicates, missing fields, offline samples, and postings that can become stale. Candidate fit also requires explicit screening constraints.

How it works

  1. 01

    Greenhouse API / offline sample

  2. 02

    Normalized job schema

  3. 03

    Deduplication + retrieval

  4. 04

    Filters + weighted ranking

  5. 05

    Drafts + application CSV

From input to output

  1. 01Fetch Greenhouse boards with bounded request timeouts and per-board error reporting.
  2. 02Normalize the schema, preserve source labels, and deduplicate records.
  3. 03Retrieve candidates with optional sentence embeddings or TF-IDF fallback, then apply hard filters and weighted ranking.
  4. 04Generate reviewable resume drafts, record feedback, and persist application status by job ID.

Data sources

  • Greenhouse public job-board API
  • Labeled offline job sample
  • User-provided resume/profile and feedback, kept outside the portfolio

Technical approach

  • Exact hash and optional fuzzy deduplication
  • TF-IDF cosine similarity or optional sentence-transformer retrieval
  • Hard filters and weighted ranking
  • CSV-backed application upserts and status updates
  • Four persona checklists and a simulated feedback benchmark

What you can inspect

  • Ranked jobs with fit explanations
  • Tailored draft application materials
  • Application tracker and CSV / Excel exports
  • Persona-check and feedback evaluation reports
  • Recorded benchmark: 424 normalized live-source job records, each with a populated application URL.
  • Four personas passed their three documented checklist checks.
  • Precision@10 remained 0.20 before and after 50 simulated feedback rounds; no recommendation-quality lift is claimed.

JobPilot demonstrates a complete data-to-review workflow with explicit source labeling and a reproducible evaluation snapshot.

Checks & engineering decisions

Verification evidence

  • Four persona checklists test screening behavior.
  • A 50-round simulated feedback test records Precision@10 before and after ranking-weight updates; both are 0.20.

Key decisions

  • Keep offline records visibly distinct from live-source records.
  • Use a TF-IDF fallback when embedding models are unavailable.
  • Store application states independently from candidate-fit scores.

Application workflow schema

python
APPLICATION_COLUMNS = [
    "job_id", "company", "title", "status", "apply_url",
    "fit_score", "created_at", "updated_at", "notes",
]

The tracker upserts by job ID, preserves the original creation time, and records status changes separately from recommendations.

Role & status

Application development, ingestion and cleaning, matching logic, explainable ranking, workflow persistence, and benchmark evaluation.

Supporting project · Hosted Streamlit app was sleeping at the latest availability check Source review: 2026-10-14.

Limitations

  • The reviewed ingestion implementation supports Greenhouse; other ATS adapters are not claimed.
  • The ingestion link label checks URL presence and format, not continued job availability or an HTTP liveness guarantee.
  • Salary, sponsorship, and seniority inference can be incomplete; generated drafts require human review.
  • The local feedback simulation is not a measured hiring outcome; CSV persistence is not multi-user account infrastructure.

Explore the evidence

Implementation evidence: technical_brief.md, benchmark_results.md, ingest_greenhouse.py, deduplicate.py, ranking.py, evaluation.py, and application_tracker.py.